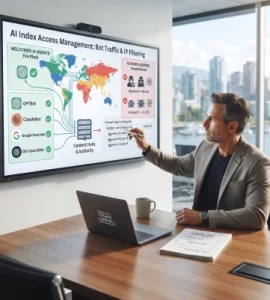
 When business owners throughout the Okanagan valley ask our Kelowna SEO team how to secure their digital assets against aggressive automated scraping, they frequently worry about losing their hard-earned content to unauthorized third-party trainers. Yet, in my over 25 years of search engine optimization experience, I have learned that locking your website down entirely is a critical strategic mistake.
Balancing open access for valuable generative search bots with robust intellectual property protection requires a nuanced technical approach. If you block all automated scrapers indiscriminately, you protect your text from data training, but you also render your business invisible within modern AI overviews and generative citations.
In this guide, we will explore how to configure robots.txt directives and security layers to welcome valuable AI agents while blocking malicious scrapers.
Why Total Blocking Destroys Your Generative Search Visibility
For years, many website administrators relied on a blanket blocking strategy – putting up rigid walls to keep every automated bot off their servers. However, the search landscape has shifted dramatically from traditional blue links to direct, conversational AI answers.
- The Citation Trade-Off: When a user asks an AI assistant for local recommendations or technical insights, the model cites the sources it trusts. If your robots.txt file or security firewall blocks search-specific AI agents, you will not be featured in those citations.
- The Distinction Between Bots: You do not need to treat every scraper the same. Modern technical optimization requires separating helpful generative discovery bots from resource-draining content scrapers and malicious AI trainers.
Configuring Robots.txt Directives for Selective AI Access
Your robots.txt file serves as the first line of engagement for automated crawlers. Rather than locking the front door to everyone, you can use explicit user-agent declarations to control who gets in.
- Welcoming Valuable Discovery Agents: Ensure that search-driven AI user agents – such as GPTBot, OAI-SearchBot, Google-Extended, and ClaudeBot – retain permission to crawl your core informational hubs and semantic content pages.
- Blocking Malicious Scrapers: Identify aggressive web scrapers, data harvesters, and unauthorized AI model trainers by their user-agent strings and explicitly disallow them at the root level.
- Balancing Protection and Indexing: Review your directives regularly to ensure your instructions remain precise, preventing accidental blocks on the specific pages you want generative engines to read and cite.
Deploying Security Layers and Rate Limiting to Prevent Scraping Overreach
robots.txt files operate on a voluntary compliance model, meaning malicious scrapers often ignore instructions entirely. To protect your server resources and proprietary data, you must implement robust security layers.
| Protection Layer | Purpose | Operational Impact |
|---|---|---|
| Cloudflare Bot Management | Detects and mitigates automated scraping behavior | Challenges or blocks non-compliant bots while passing verified search agents |
| Server-Level Rate Limiting | Prevents rapid-fire requests from single IP addresses | Stops aggressive data harvesting scripts from overwhelming your server resources |
| User-Agent Validation | Verifies the legitimacy of incoming crawler traffic | Ensures bots claiming to be major search engines match valid IP ranges |
| Custom Firewall Rules | Blocks known malicious Autonomous System Numbers (ASNs) | Keeps bad-faith scrapers and content cloners away from your database |
Conclusion
Protecting your intellectual property in an era of automated scrapers does not mean shutting your doors to generative search engines. By configuring precise robots.txt directives, deploying advanced rate-limiting security layers, and selectively welcoming verified AI discovery bots, you safeguard your server while maximizing your brand visibility.
Implement these protective frameworks today, maintain control over your digital assets, and secure your place in the future of search.
Frequently Asked Questions About AI Scraping Protection
Rob is an SEO strategist and digital marketer who has been active in the search engine optimization industry since 2001. With over two decades of experience, he has witnessed the evolution of search from the early days of keyword stuffing to the modern era of AI-driven intent.
His expertise lies in technical SEO, content strategy, and authority building. He specializes in helping websites navigate complex algorithm shifts by focusing on high-quality, human-centric content and robust E-E-A-T principles. Throughout his career, he has successfully managed digital growth for a diverse range of industries – providing a grounded and historical perspective that few in the field possess.
When he is not analyzing search trends or optimizing site architecture, he is often traveling and exploring the outdoors.
Let’s Work Together
TELL US MORE ABOUT YOUR PROJECT
Let us help you get your website found. Or, if you simply have a few questions, then fill out the form below and we will get back to you.